Score matching and diffusion
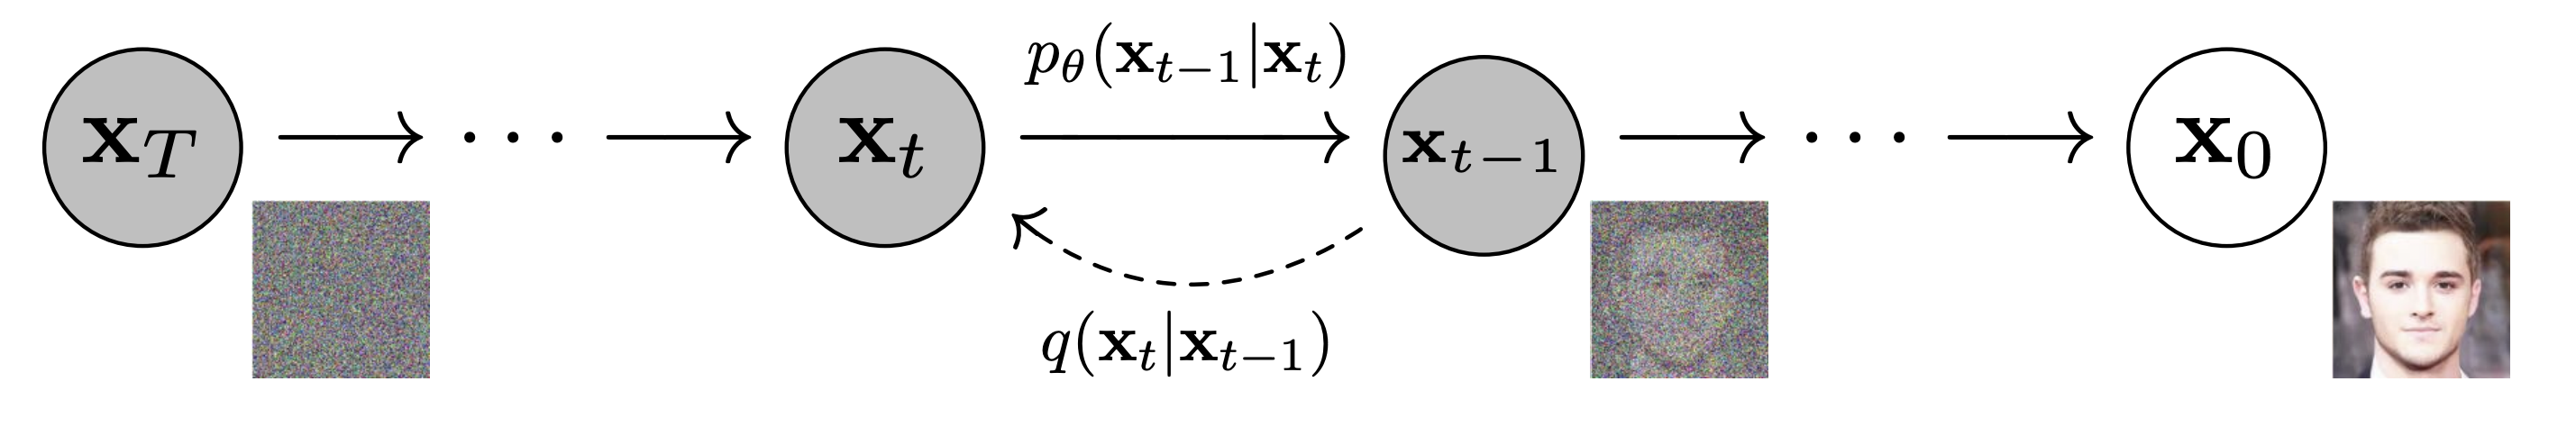
The setup goes back to Sohl-Dickstein et al. [1]. The forward chain takes data
Score matching
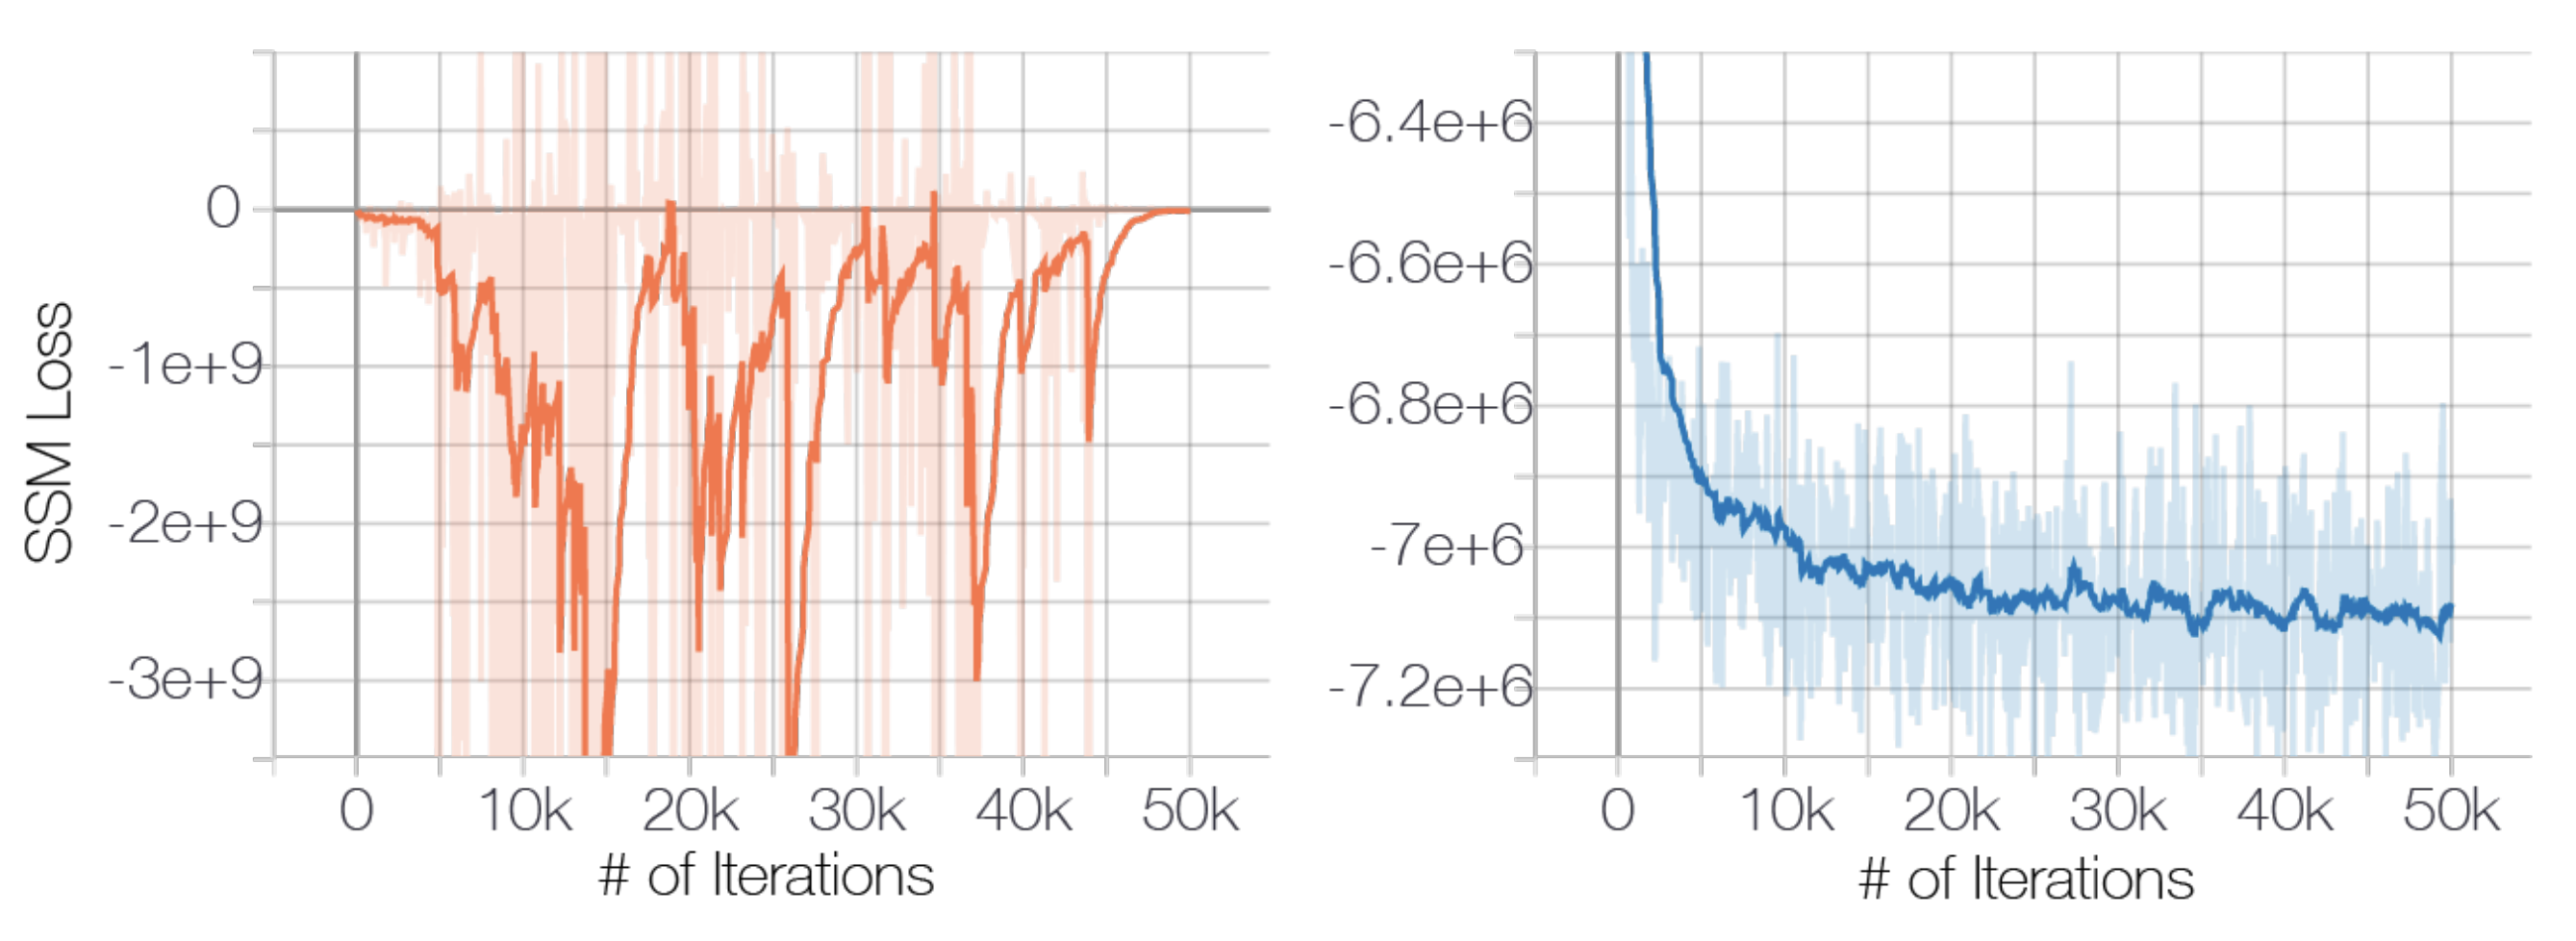
The DDPM forward chain has a clean dual under score matching, and once the two are placed side by side they are not separate ideas. The score function
Song and Ermon [2] estimated these scores at a sweep of noise levels and used annealed Langevin dynamics to draw samples from the estimates. Ho, Jain, and Abbeel showed that DDPMs trained with a weighted variational bound reduce, in a particular weighting limit, to denoising score matching at multiple noise levels. The point shared by both: learning to predict the noise that was added at a given level is enough to recover the score of the noisy distribution at that level, and sampling is then iterated denoising along the noise schedule.
SDE view
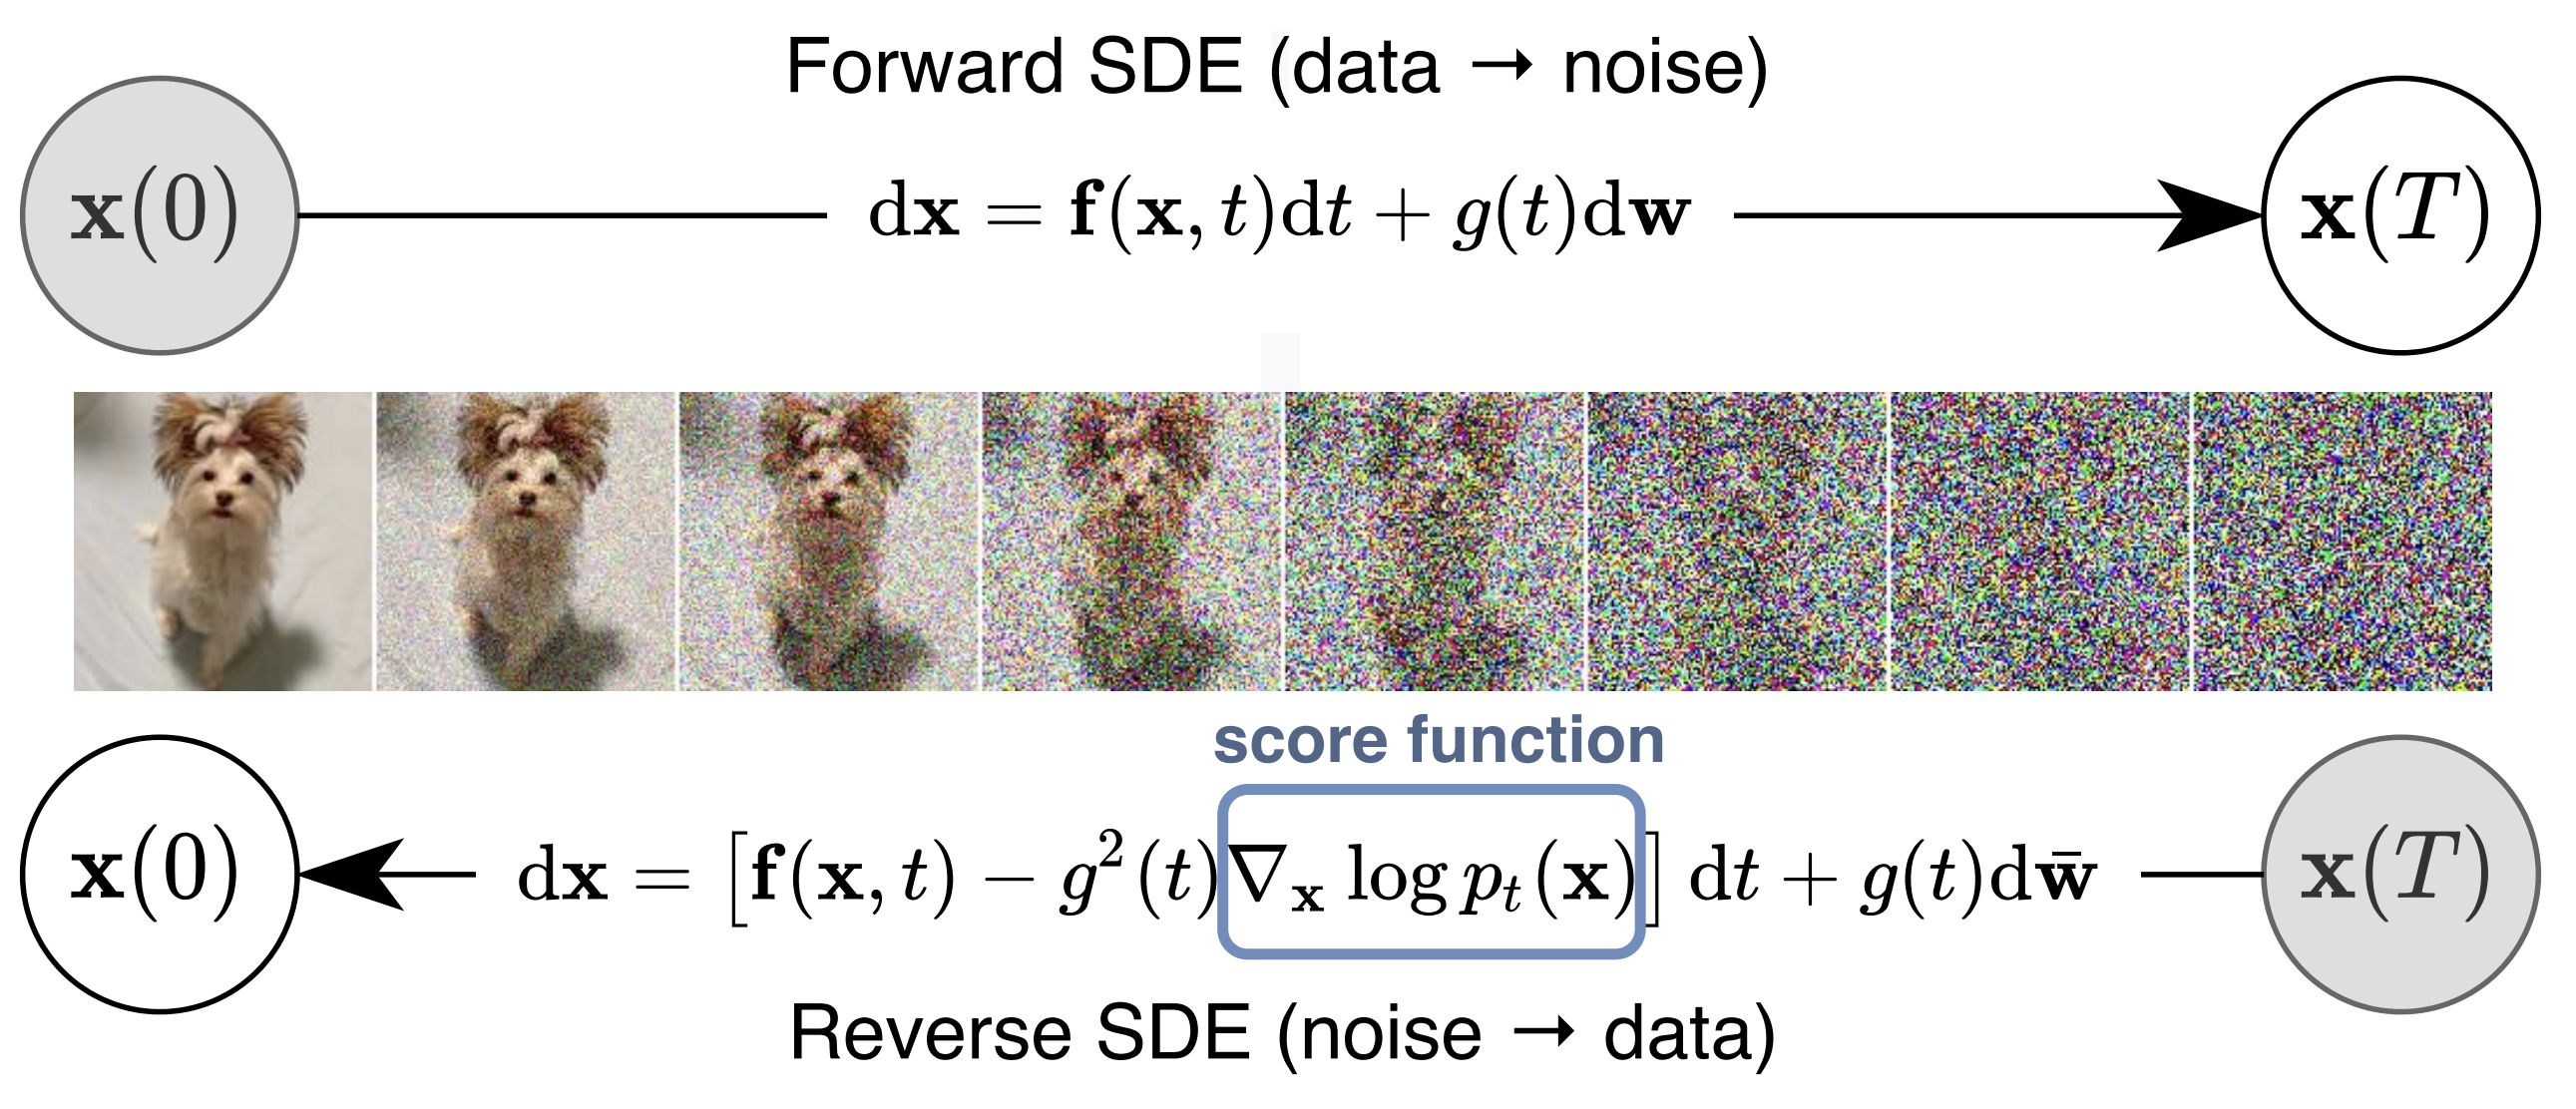
Song et al. unified the discrete and score-based views inside stochastic differential equations. The forward process is an Itô SDE
The SDE view also separates modeling from numerics. The noise schedule, solver, parameterization, and preconditioner can all be changed without touching the underlying problem of learning the score.
There is a lot of great writing on flow matching out there all of a sudden! This post clarifies the connection with diffusion models -- they are essentially two different ways to describe the same class of models. x.com/RuiqiGao/status/1863653647961428465
Sander Dieleman @sedielem,
Lu et al. [6] built DPM-Solver out of the semi-linear structure of the probability-flow ODE and cut sampling from thousands of steps to tens, with no retraining required.
Karras et al.
Karras et al. [5] argued that diffusion practice had become unnecessarily entangled: sampling schedule, loss weighting, noise parameterization, network preconditioning, and solver choice were all bundled together. Pulling each design decision apart showed that most of the published performance gains came from untangling the design space, not from a new generative principle. Their EDM recipe (continuous noise levels indexed by
| VP | VE | iDDPM + DDIM | Ours (“EDM”) | |
|---|---|---|---|---|
| Sampling | ||||
| ODE solver | Euler | Euler | Euler | 2nd order Heun |
| Time steps |
||||
| Schedule |
||||
| Scaling |
||||
| Network and preconditioning | ||||
| Architecture of |
DDPM++ | NCSN++ | DDPM | (any) |
| Skip scaling |
||||
| Output scaling |
||||
| Input scaling |
||||
| Noise cond. |
||||
| Training | ||||
| Noise distribution | ||||
| Loss weighting |
||||
| Parameters | ||||
| Parameters | ||||
The implementation history runs through three papers. Dhariwal and Nichol showed that diffusion models beat GANs on ImageNet, by combining classifier guidance with architecture and training changes. Ho and Salimans then dropped the auxiliary classifier in favor of classifier-free guidance, training the conditional and unconditional scores jointly and combining them at sampling time. Rombach et al. moved the diffusion process inside the latent space of a pre-trained autoencoder, which is what made high-resolution diffusion feasible at academic compute and what Stable Diffusion is built on.
Natural data concentrates near low-dimensional manifolds where direct density modeling is hard. Adding white noise thickens the manifold: at high noise levels the distribution is smooth, at low noise levels it is detailed but local. Diffusion replaces a single full-density estimation problem with a sequence of denoising problems indexed by noise level. Compare with autoregressive models, which generate sequentially conditioned on prior tokens, and with flows, which accept restrictions on the transforms they can express in exchange for tractable likelihoods. Diffusion's training objective is stable in a way GAN training is not, while paying for it with iterative sampling that DPM-Solver, consistency models, and distillation have largely clawed back.
Semantic abstraction inside the model is still theoretically incomplete. The score tells you how to move from a noisy sample toward a clean one. It does not say why text prompts, latent-space guidance, or multimodal conditioning organize concepts the way they do. Those mechanisms are built on top of a fixed score-matching core, but the core does not force any of them.
Whether diffusion is the right parameterization is also unclear to me. Flow matching frames generation as learning a vector field that transports a simple prior to the data distribution along possibly non-straight paths, with a regression objective that does not require an SDE. Rectified flow constrains the paths to be nearly straight, which keeps few-step sampling accurate. Consistency models compress the iterative denoising sampler into a single-step generator while preserving sample quality. None of these compete with score-based modeling; they are alternative parameterizations of the same vector-field-across-noise-levels problem.
Further reading
- P. Dhariwal and A. Nichol. Diffusion models beat GANs on image synthesis. arxiv 2105.05233, 2021
- J. Ho and T. Salimans. Classifier-free diffusion guidance. arxiv 2207.12598, 2022
- R. Rombach, A. Blattmann, D. Lorenz, P. Esser, and B. Ommer. High-resolution image synthesis with latent diffusion models. arxiv 2112.10752, 2021
- Y. Lipman, R. T. Q. Chen, H. Ben-Hamu, M. Nickel, and M. Le. Flow matching for generative modeling. arxiv 2210.02747, 2022
- X. Liu, C. Gong, and Q. Liu. Flow straight and fast: learning to generate and transfer data with rectified flow. arxiv 2209.03003, 2022
- Y. Song, P. Dhariwal, M. Chen, and I. Sutskever. Consistency models. arxiv 2303.01469, 2023
- A. Hyvärinen. Estimation of non-normalized statistical models by score matching
- P. Vincent. A connection between score matching and denoising autoencoders
References
- [1] J. Sohl-Dickstein, E. A. Weiss, N. Maheswaranathan, and S. Ganguli. Deep unsupervised learning using nonequilibrium thermodynamics. arxiv 1503.03585, 2015.
- [2] Y. Song and S. Ermon. Generative modeling by estimating gradients of the data distribution. arxiv 1907.05600, 2019.
- [3] J. Ho, A. Jain, and P. Abbeel. Denoising diffusion probabilistic models. arxiv 2006.11239, 2020.
- [4] Y. Song, J. Sohl-Dickstein, D. P. Kingma, A. Kumar, S. Ermon, and B. Poole. Score-based generative modeling through stochastic differential equations. arxiv 2011.13456, 2020.
- [5] T. Karras, M. Aittala, T. Aila, and S. Laine. Elucidating the design space of diffusion-based generative models. arxiv 2206.00364, 2022.
- [6] C. Lu, Y. Zhou, F. Bao, J. Chen, C. Li, and J. Zhu. DPM-Solver: a fast ODE solver for diffusion probabilistic model sampling in around 10 steps. arxiv 2206.00927, 2022.